
Video chapters
- AppEngine Sites and Pages
- How a visitor address becomes a page
- Prepare the organization and staff client
- Select a site and understand creation
- Create the page record and content record
- Open the saved page in Build Studio
- Read the page and its attached post
- Bind the design to the right data
- See the saved content change on the page
- Saving and publishing are different
- Publish, revise and unpublish through the API
- Page publication does not freeze every data source
- Home pages, nested paths and missing content
- Link an enabled site feature
- Platform address, custom domain and your renderer
- Find the failed layer without changing everything
- Continue with the complete examples
Written guide
Companion source code
Get the course source code on GitHub. The folder includes the supplied examples and setup instructions. Keep credentials in your own environment; use the maintained API reference when adapting recorded request examples.
Build a content-driven website on AppEngine: select its site, create a page and article, resolve a visitor path, bind the returned content, and control whether the working or published design is served. The examples use one Cedar & Form journal throughout so you can follow each record into its visible result.
Watch the course review video · Download complete requests, journal and server renderer
Before you begin
Open Appmint Studio and select an organization you can edit. For the exact staff sign-in procedure, use Database and Repository APIs, chapter 2 and its written course. You need the returned bearer token, its organization ID, your deployment's API origin, and permission to edit content. A customer session from API Foundations is not a substitute for staff administration rights. Site creation and feature linking also require the applicable Content Admin or Configuration Admin role.
Use the hosted API reference to inspect your deployment's current contract. The video keeps TypeScript, JavaScript, Python, curl, Postman and JSON together; these are equivalent client examples, not six independently executed tests. Every successful result identified as observed came from the isolated training deployment.
Keep Authorization: Bearer YOUR_TOKEN, orgid: YOUR_ORGANIZATION_ID, and Content-Type: application/json together for JSON writes. Keep privileged credentials in your development client or server environment. The authentication and organization isolation manuscript explains application identities for your own deployed renderer. It is linked as written material, not an available video.
1. Understand site, page and content
A site chooses its hostname mappings, home page and serving policy. A page holds a design and route identity. A post holds the article. They are separate records with separate identifiers.

For a conceptual address https://your-site.example.com/journal/room-lighting, the hostname selects a site, journal selects a page, and room-lighting selects a post when the page's content datatype is post. The example hostname is explanatory, not a deployed training address.
Our actual page machine name is journal-sites1010, and the article slug is room-lighting-1010. Substitute the names and IDs returned in your own organization. The API response is not itself a website: a renderer must use its HTML or data to produce the browser document.
2. Select your site, or prepare a new one
In Studio, open Build Studio, select the intended site, then inspect the current site name before opening a page. From its dashboard, Sites & dev environments opens Site Management. New Site opens the real creation form with Site Name, Title, Description, and Domain (Optional). Complete that form only when you intend to create the site; the course inspects it without submitting.

Read the selected site with GET /site/get-site/{siteName}/{hostname} and inspect data.name, data.homePage, and data.publishedPagesOnly. Inspect registered mappings with GET /site/get-site-host-mappings/{siteName}. Do not derive a public hostname merely by guessing its format.
The compatibility POST /site/create action accepts:
{
  "name": "your-site",
  "title": "Your Site",
  "description": "Your site description",
  "homePage": "home",
  "publishedPagesOnly": true
}
Optional template and domainName belong only when you have chosen them. The current controller describes this endpoint as legacy; the newer POST /site/add contract uses siteName rather than name. Consult the exact endpoint you use instead of swapping payload names. Creation validates plan limits and can register hostnames and send notifications. Neither creation endpoint was executed in this recording. We reused the existing isolated training site vidsite.
Before relying on an address, inspect the actual creation response, mappings, GET /site/base-url?siteName=..., and the browser result. A registered mapping is not evidence that public DNS, TLS and hosting are working.
3. Create the article and the design
Create a post record through the Repository API. The full downloadable request contains data.title, data.name, data.slug, data.summary, data.content, and the example author. Save its returned sk. Our initial title is A calmer room starts with light.
Create a separate page record with the supplied complete journal.html:
{
  "datatype": "page",
  "data": {
    "site": "YOUR_SITE_NAME",
    "name": "journal",
    "slug": "journal",
    "title": "Cedar & Form Journal",
    "datatype": "post",
    "html": "THE_COMPLETE_HTML_DOCUMENT"
  }
}
The actual HTML is a full responsive document in the ZIP; the string above is only a label. Replace it with the document content in your client. Outer datatype: page chooses the repository collection. Inner data.datatype: post tells site routing what content the next segment identifies.
Use PUT /repository/create, preserve the returned page ID, then read GET /repository/get/page/{pageId}. A successful create response alone does not prove that a public visitor can see the page.
4. Open that exact saved page
Return to Build Studio, confirm the site, locate Cedar & Form Journal, and choose its edit control. The recording shows this real navigation and the saved design opening in the editor. It does not substitute a mockup for the application.
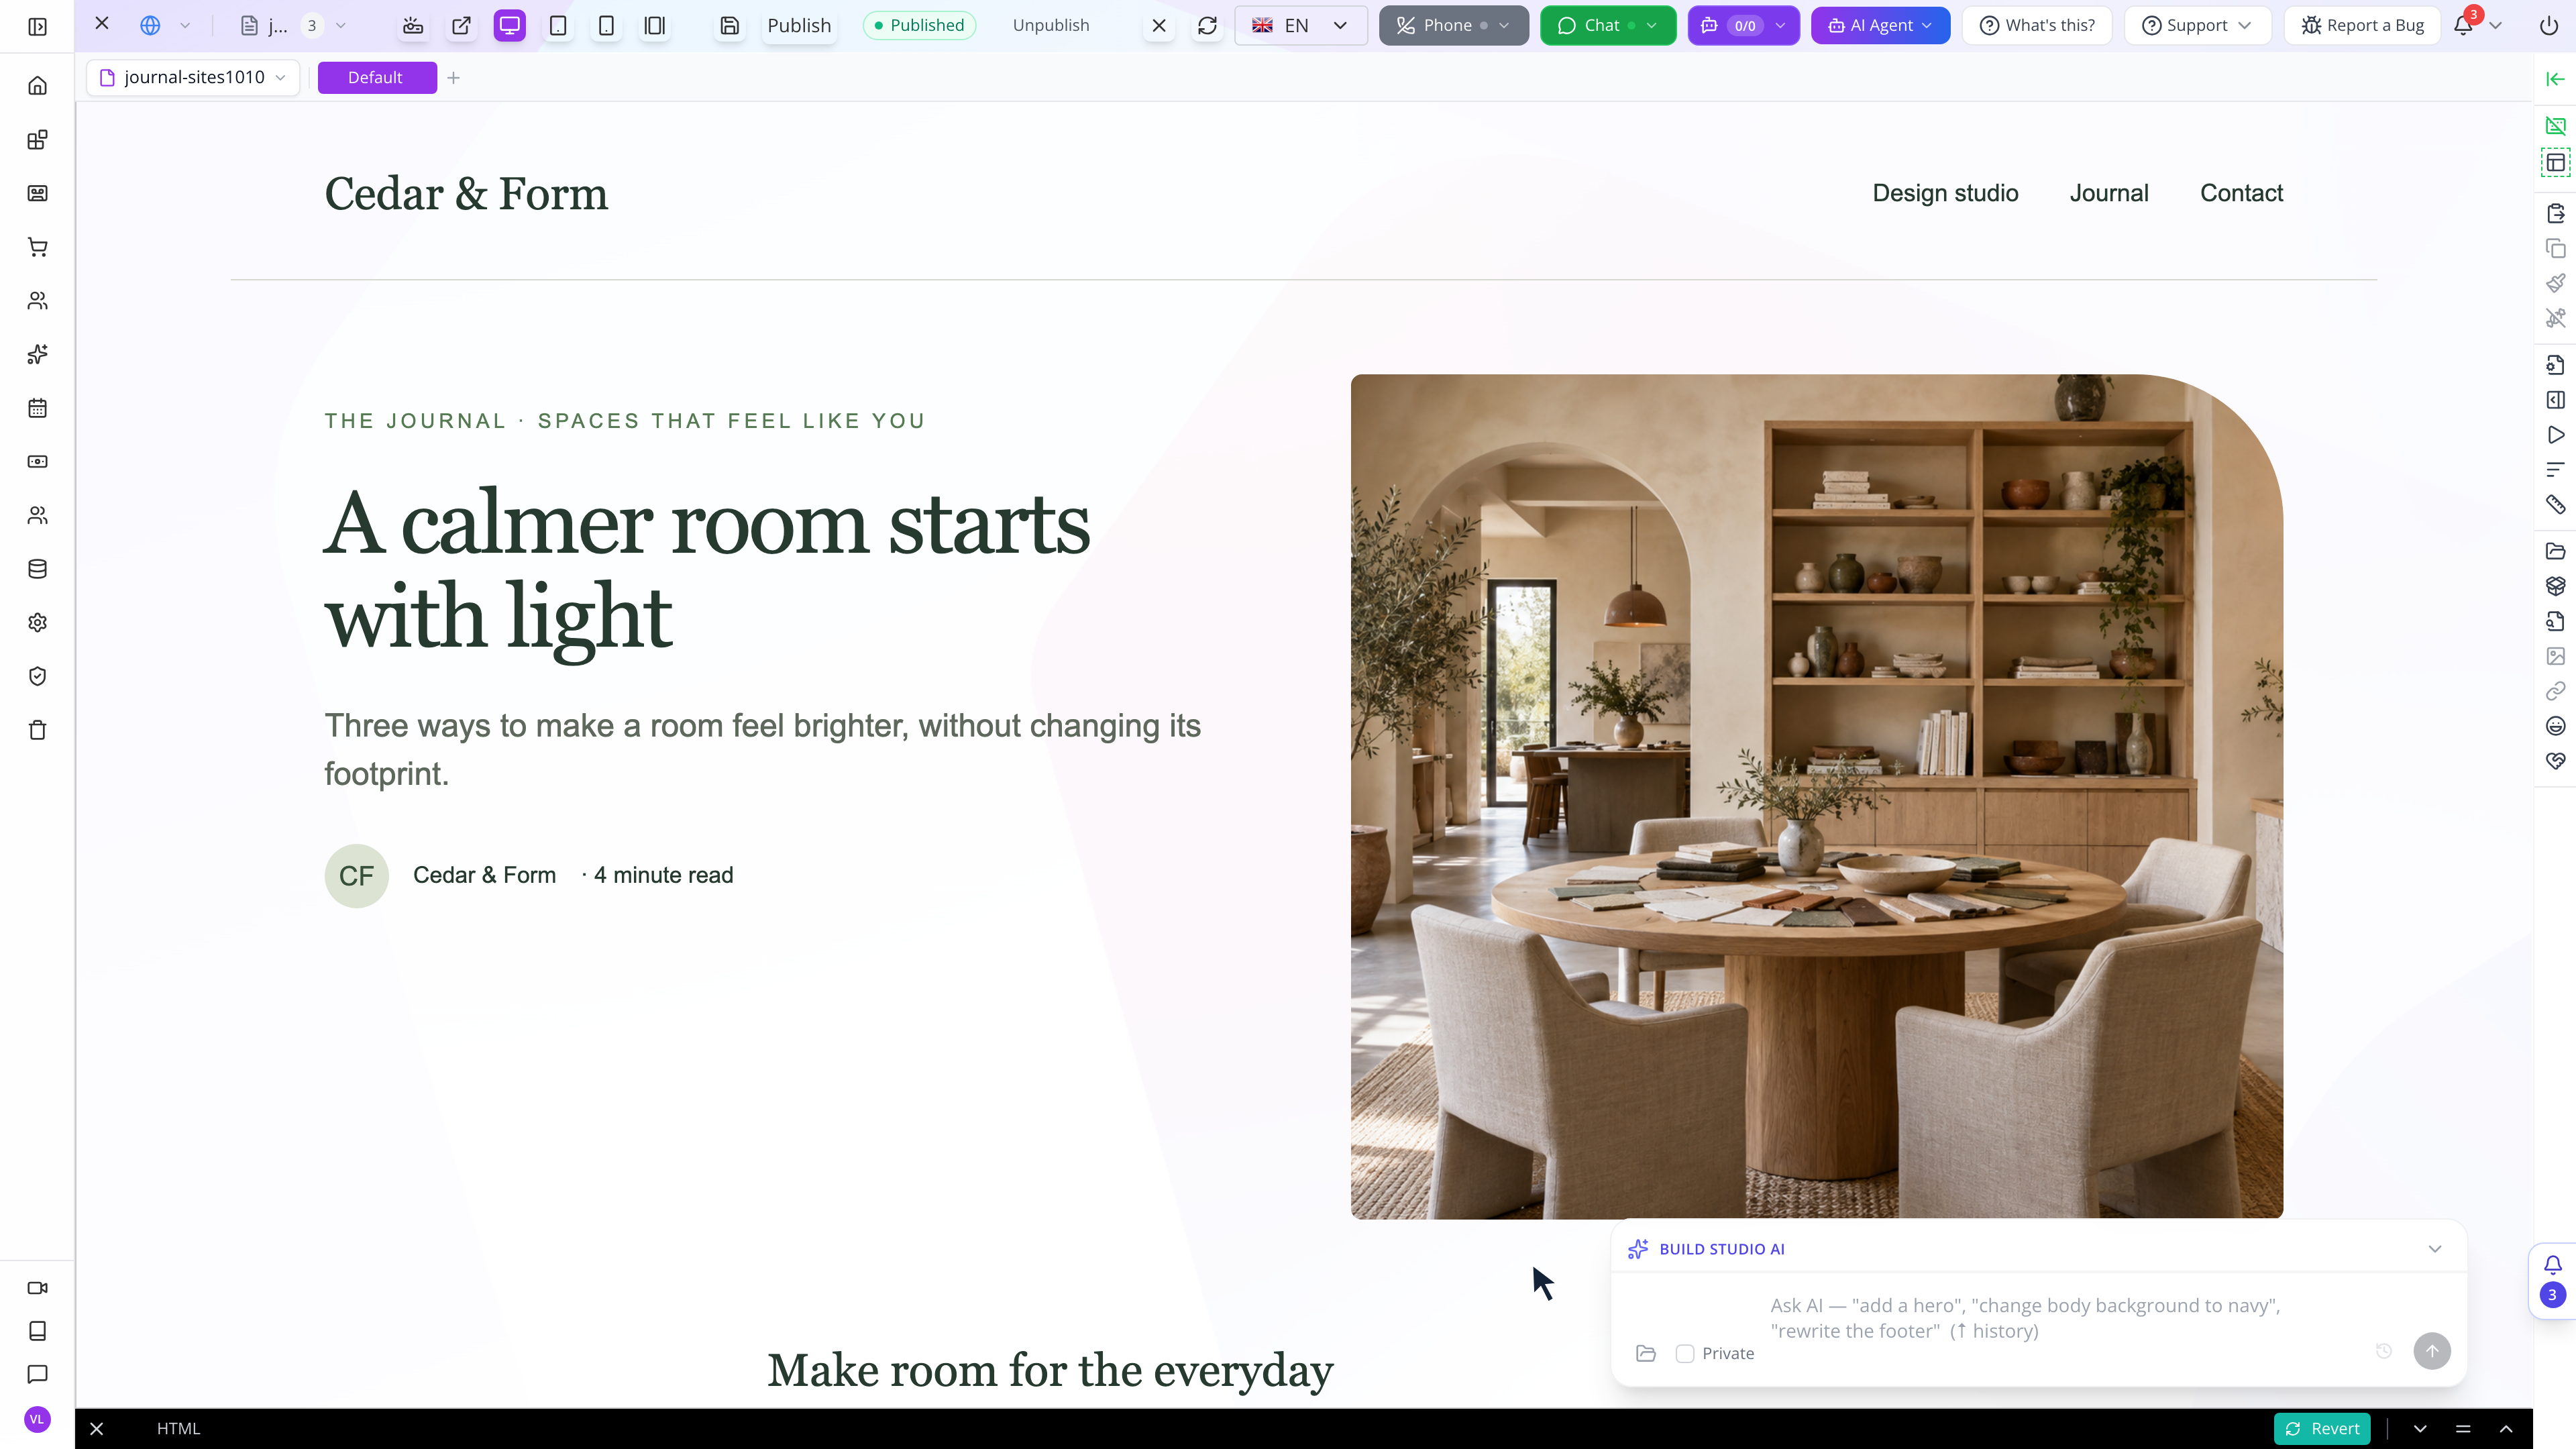
For visual authoring, HTML editing, responsive controls, and recovery, continue with Build Studio. This course concentrates on the platform contract behind those designs.
5. Resolve a page and its attached content
Call:
GET /site/page/{hostname}/{siteName}/journal/room-lightingUse your actual mapped hostname, site name and saved page route. Inspect the returned sk, data.site, requestPath, and requestData.data. In the verified example, the last property contains the matching post. The full response includes the article body; the video selects only relevant fields to remain readable.
An attached record is data for a renderer. It does not automatically replace every heading in arbitrary HTML. A design must explicitly bind a field, or your application must render that field itself.
6. Choose a binding approach
The supplied journal contains Appmint runtime bindings:
<div data-source="repository.findAnyId"
     data-source-payload='{"datatype":"post","id":"{{path.last}}"}'>
  <h1 data-bind="data.title"></h1>
  <p data-bind="data.summary"></p>
  <div data-bind-html="data.content"></div>
</div>
The source reads the post identified by the final path segment. Text bindings escape text; HTML bindings render markup. Only use trusted or sanitized editorial HTML. A general public submission should not become trusted article HTML by default.
This runtime lookup is separate from the record attached to /site/page. A server-rendered application can consume page.requestData.data[0].data directly, avoiding a second lookup. The live demonstration uses this explicit course server renderer. It is not a claim that the separate base-app runtime was successfully deployed or anonymously verified.
7. Run the included server-renderer example
The ZIP includes course-renderer.mjs. It uses the real site response, binds the journal's heading and summary as escaped text, and places trusted article content in the body. It is deliberately scoped to the supplied journal's binding contract; it is not a universal HTML template engine.
Set API_BASE, SITE_HOST, SITE_NAME, ORG_ID, and APP_TOKEN in your shell or server configuration. APP_TOKEN must represent an authorized identity for your deployment. Run node course-renderer.mjs; it binds only to the loopback interface, with PORT optional. Visit the path matching your saved page and article. The README provides the exact environment-variable template. No usable credential is shipped.
The controlled recording used an existing authorized staff session through a server-only, read-only local transport. That transport is a rehearsal fixture, not a hosted authentication recommendation. Anonymous access, public DNS/TLS, and a production app credential were not verified.

The procedure first renders A calmer room starts with light. A Repository partial update changes the same post's title to Natural light, thoughtfully layered and its summary to Start with daylight. Add task lighting. Finish with a warm accent. Reloading the same page shows both changes. The design remains the same. This demonstrates actual saved content flowing through the site response into the browser.
8. Separate saving, publishing and serving policy
Saving changes the working page record. Publishing creates or refreshes its serving copy. The site's publishedPagesOnly setting determines which copy site routing chooses.

With publishedPagesOnly: true, a draft page is not selected by the serving route. An unpublished source can still exist for editing. With the setting false, site routing can select the working page, including a draft. Consequently, Unpublish is not a privacy control for a draft-serving site. Choose the policy deliberately and inspect the intended viewer's result.
9. Follow the verified publication lifecycle
The examples package contains the actual requests and selected responses for this sequence:
- Read the route before publishing under a published-only policy: 404.
POST /repository/publish/page/{pageId}; read the same route: 200.POST /repository/update-partial/page/{pageId}with a reviseddata.title.- Read the staff source: the revised title is present. Read the serving route: the previous title remains.
- Publish again. The serving response now contains the revised title.
- Publish again without changing content: the response reports already published.
POST /repository/unpublish/page/{pageId}. The source remains readable, while the published-only serving route returns 404.
The rehearsal restored the original site policy afterward and republished the owned page. Under the original draft-serving policy, a separate unpublish test still returned the working page, confirming why the setting matters. Do not modify another site's serving policy just to reproduce the lesson.
10. Content publication is a separate concern
A published page snapshots its design, not every record it might read. We changed the article and observed a fresh page response carrying the changed title and summary while the page HTML stayed unchanged.
The site's published-only flag selects page copies. Do not assume it filters every bound collection to published content. Use the content route's supported publication filter and access policy, then test the exact visitor session. The staff-authenticated results in this course do not establish what an anonymous visitor can read.
11. Understand route alternatives and missing content
An empty path uses the site's homePage. With child navigation enabled, the next segment selects a child page according to the service's routing rules. Without a page content datatype, the remaining path can instead specify a datatype and identifier. These alternatives are documented, not individually rehearsed here; test their behavior against your actual hierarchy before designing public links.
The rehearsed missing-page request returned 404. The missing-post request returned the page successfully with requestData.data: []. Your renderer must handle the empty array. The included example returns an article-not-found response rather than displaying old fallback text as though it were the requested article.
Hostname lookup can fall back to a named or default site. Check the returned site identity, not only HTTP 200. A successful response from the wrong default site is still a routing mistake.
12. Link an enabled site feature
Enable and configure the intended feature first. The verified isolated example had the forms feature pointing to its configured page and a real footer in its design.
POST /site/{siteName}/features/forms/link{"where":"footer","label":"Contact us"}Read updated, alreadyLinked, and noPlace; inspect the saved page HTML. A page without the requested insertion point cannot receive a footer link there. The recorded request inserted the link and a fresh repository read confirmed it. Sending the same options with "remove": true removed it.
This operation edits working page designs across the selected site. Use a deliberately isolated site while learning. Publish affected pages if your serving policy requires it. Linking a form destination is not the same as demonstrating a form submission; no external message was sent.
13. Hosting and the wider Site API
GET /site/base-url is the starting point for links; it is not proof of live hosting. For production, validate the hostname mapping, DNS, certificate, renderer configuration, and intended access identity. Keep credentials server-side.
The wider Site controller also provides organization/hostname lookup, company context, organization site listing, template creation/application, cloning, sitemap generation, app DSL retrieval, direct page-data reads, domain attachment/change/removal, and plan/usage inspection. Those operations are not silently equivalent to creating a repository site record. Several have infrastructure or notification side effects.
Use Site Management for domain and hosting configuration, and the current API reference for each exact payload. The course's endpoint inventory in the ZIP lists all current Site controller routes so these capabilities remain discoverable. Domain deployment, template application, cloning, removal, and sitemap publishing were not executed in this rehearsal.
14. Diagnose the failed layer
Check resolved site → selected page → attached record → binding → serving policy → hosting. Compare IDs and exact fields at each step.
- Wrong site: inspect hostname mapping, explicit site name and fallback behavior.
- Missing page: inspect site membership, route identity and published-only selection.
- Empty article: inspect content datatype, slug/ID and
requestData.data. - Right data but wrong heading: inspect the actual binding or server mapping.
- Saved revision not served: compare working and published copies before assuming browser caching.
- Unreachable address: investigate DNS, TLS and renderer configuration.
Keep a successful request beside the visible browser result. The underlying API, the Studio canvas, and an anonymous hosted site are different kinds of evidence.
Verification and limits
Verified locally: page/post creation and readback, current Studio navigation and design, site/hostname reads, attached content resolution, full publication lifecycle, draft-serving behavior, changed article readback and actual custom-renderer browser outcome, feature-link insertion/removal, missing page and missing record responses. Site creation form was inspected but not submitted. All production captures originate at CSS 1920×1080 with DPR 2 and are delivered at 2560×1440, 30 fps.
Not established: public deployment, anonymous rendering, production app identity, base-app runtime startup, domain or infrastructure changes, child-page and explicit-datatype alternative rehearsals, and all six language clients executing independently. The isolated base-app startup failed on its local Next/CSS dependency configuration; no application source was changed to conceal it. The custom course renderer is shipped and explicitly identified.