
Video chapters
- 0:00 Welcome
- 0:17 How import and export work
- 0:47 Part 1 · Prepare the file: explained
- 1:05 Part 1 · Prepare the file — paste and preview the rows
- 1:36 Part 2 · Map the columns and validate: explained
- 1:53 Part 2 · Map the columns and validate — Event guests, mapping, Validate only
- 2:36 Part 3 · Import and check the records: explained
- 2:49 Part 3 · Import and check the records — import with errors, the saved guests
- 3:18 Part 4 · Fix and re-run without duplicates: explained
- 3:33 Part 4 · Fix and re-run without duplicates — corrected rows matched on Email
- 4:09 Part 5 · Export CSV and JSON: explained
- 4:21 Part 5 · Export CSV and JSON — JSON from the Data tab, CSV from All Collections
- 4:44 Wrap-up
Written guide
What you will learn
Appmint Data Import moves structured data into collections. We will inspect a small input, map its fields, validate without writing, then import and update the same records without creating duplicates.
1. Prepare a recognizable small input
Why this matters
Start with a few rows whose identifiers and expected values you can check. Importing into the wrong collection is harder to fix than correcting a preview.
Steps
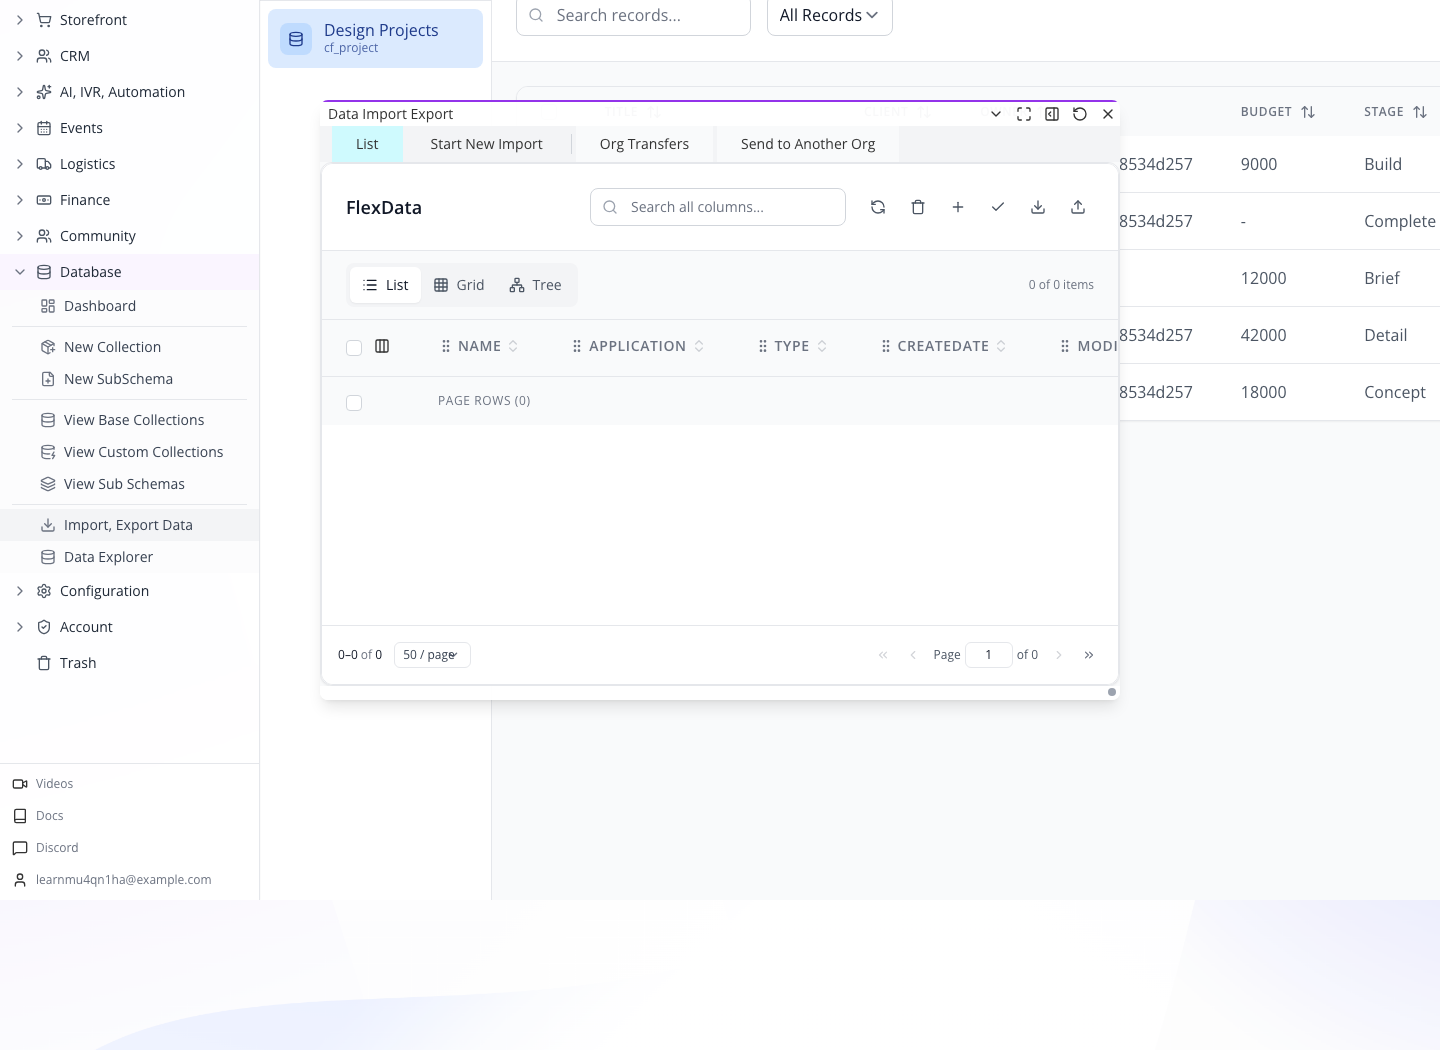
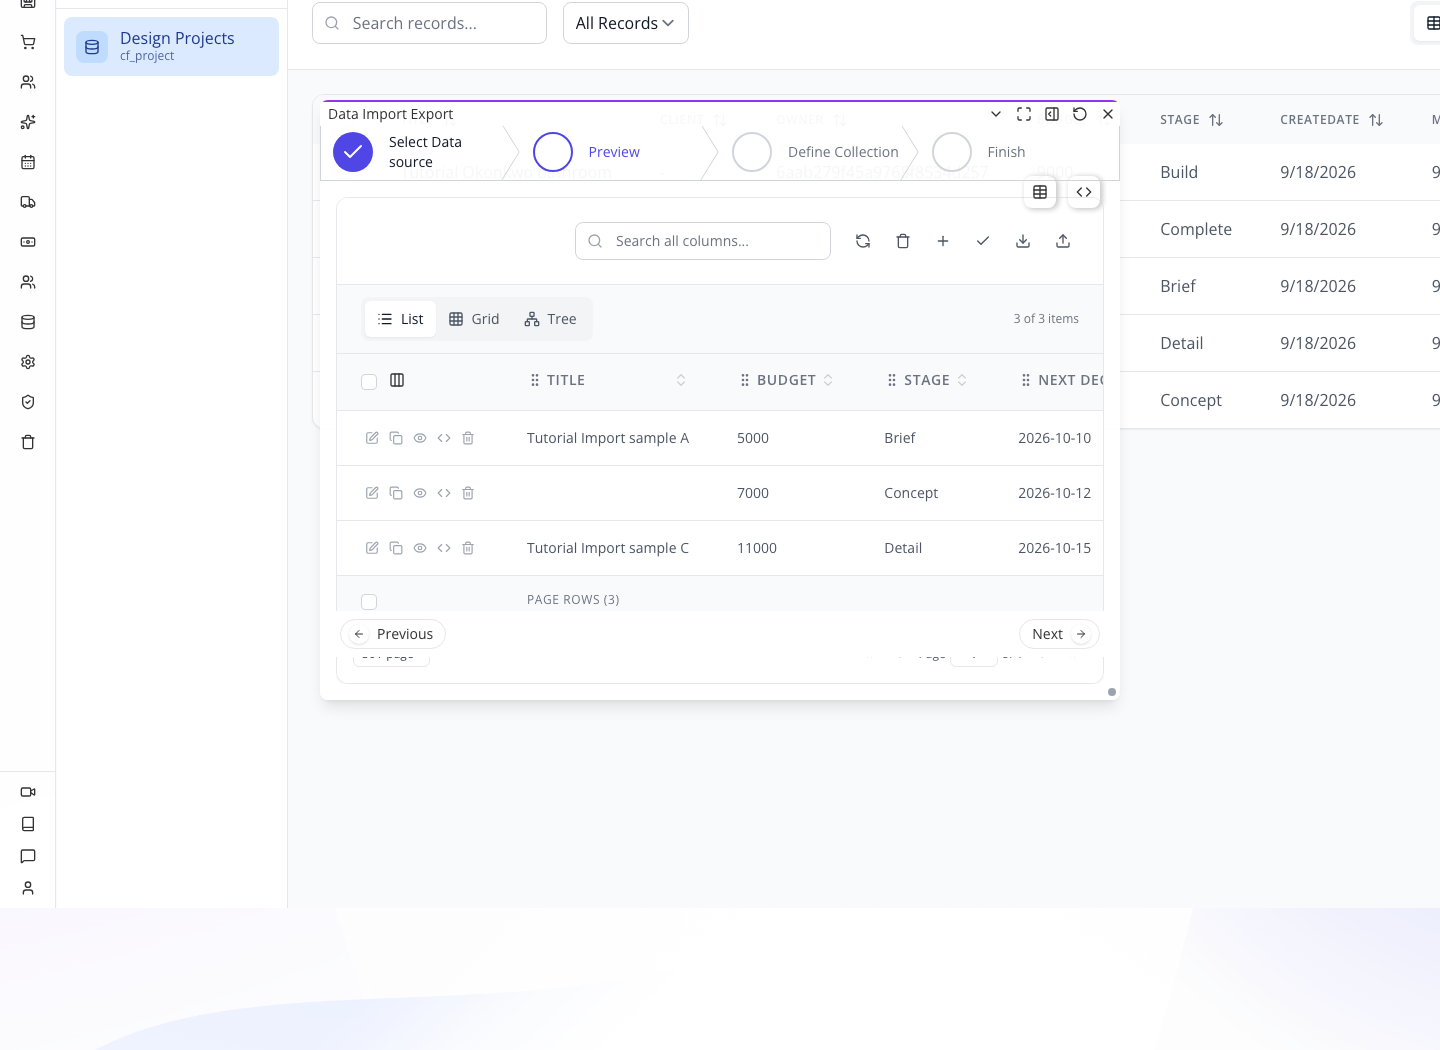
Open Database → Import, Export Data and choose Start New Import. Choose Paste JSON or CSV for a small controlled sample. Use the selected collection’s actual field names and include a stable field such as a unique reference already supported by its schema. Continue to Preview and inspect the parsed rows, column names and count. Fix invalid JSON, CSV headings or unexpected splitting before continuing. Do not assume a generated sample represents your production schema.
Check the result: Rows and values match the input rather than merely parsing without error.
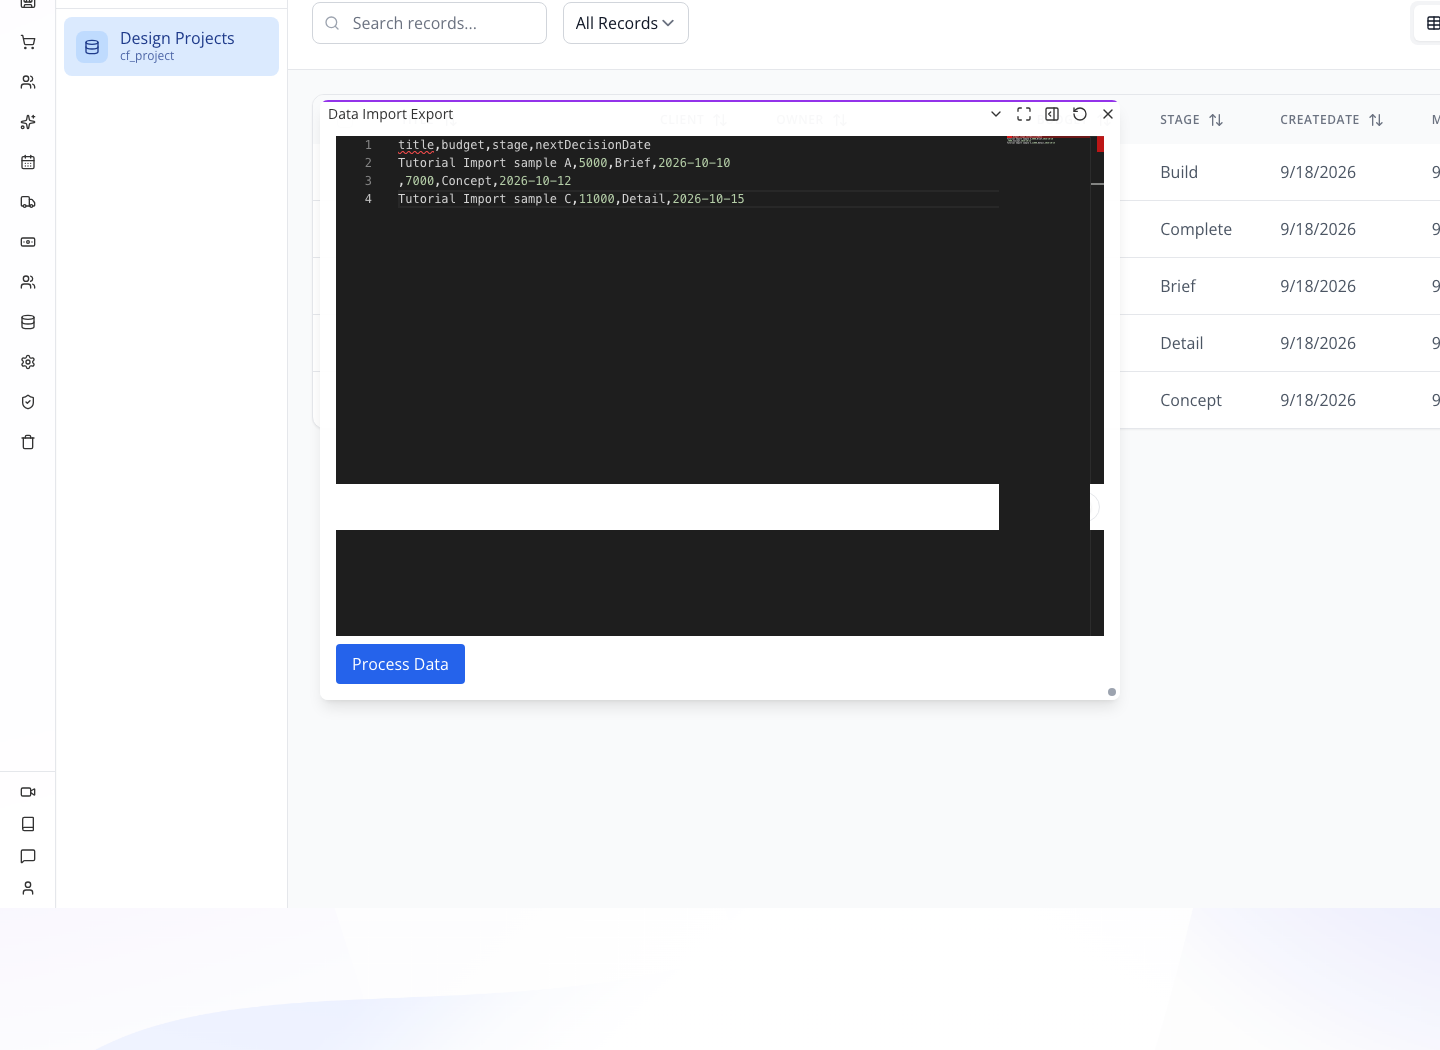
Use Process Data to parse the input, then inspect Preview. The recorded sample intentionally left the second title blank. A preview can display an invalid business row; parsing CSV is not schema validation.
For a small exercise matching the historical cf_project schema, prepare:
title,budget,stage,nextDecisionDate
Import practice A,5000,Brief,2026-10-10
Import practice B,7000,Concept,2026-10-12
Import practice C,11000,Detail,2026-10-15
Only use this example with a collection defining those fields and choices. For another collection, substitute its real identifiers and required fields. Use a schema-supported unique reference for a production update match; the readable title is not automatically unique.
2. Choose the collection and map the text input
Why this matters
The destination determines field types and validation. A new collection is a different decision from adding records to an existing collection.
Steps
Select the intended existing collection. Inspect the field-mapping view: matching names are mapped automatically; unmatched fields initially remain ignored on the text mapping path. Map each required source column to its intended target and deliberately leave irrelevant columns ignored. Check numbers, dates, reference values and nested structures against the target schema. If creating a new collection, choose that path and enter its collection name/title and field definitions before continuing; do not create a second collection simply because the original is not selected.
Check the result: The summary names the intended collection and displays the planned mappings.
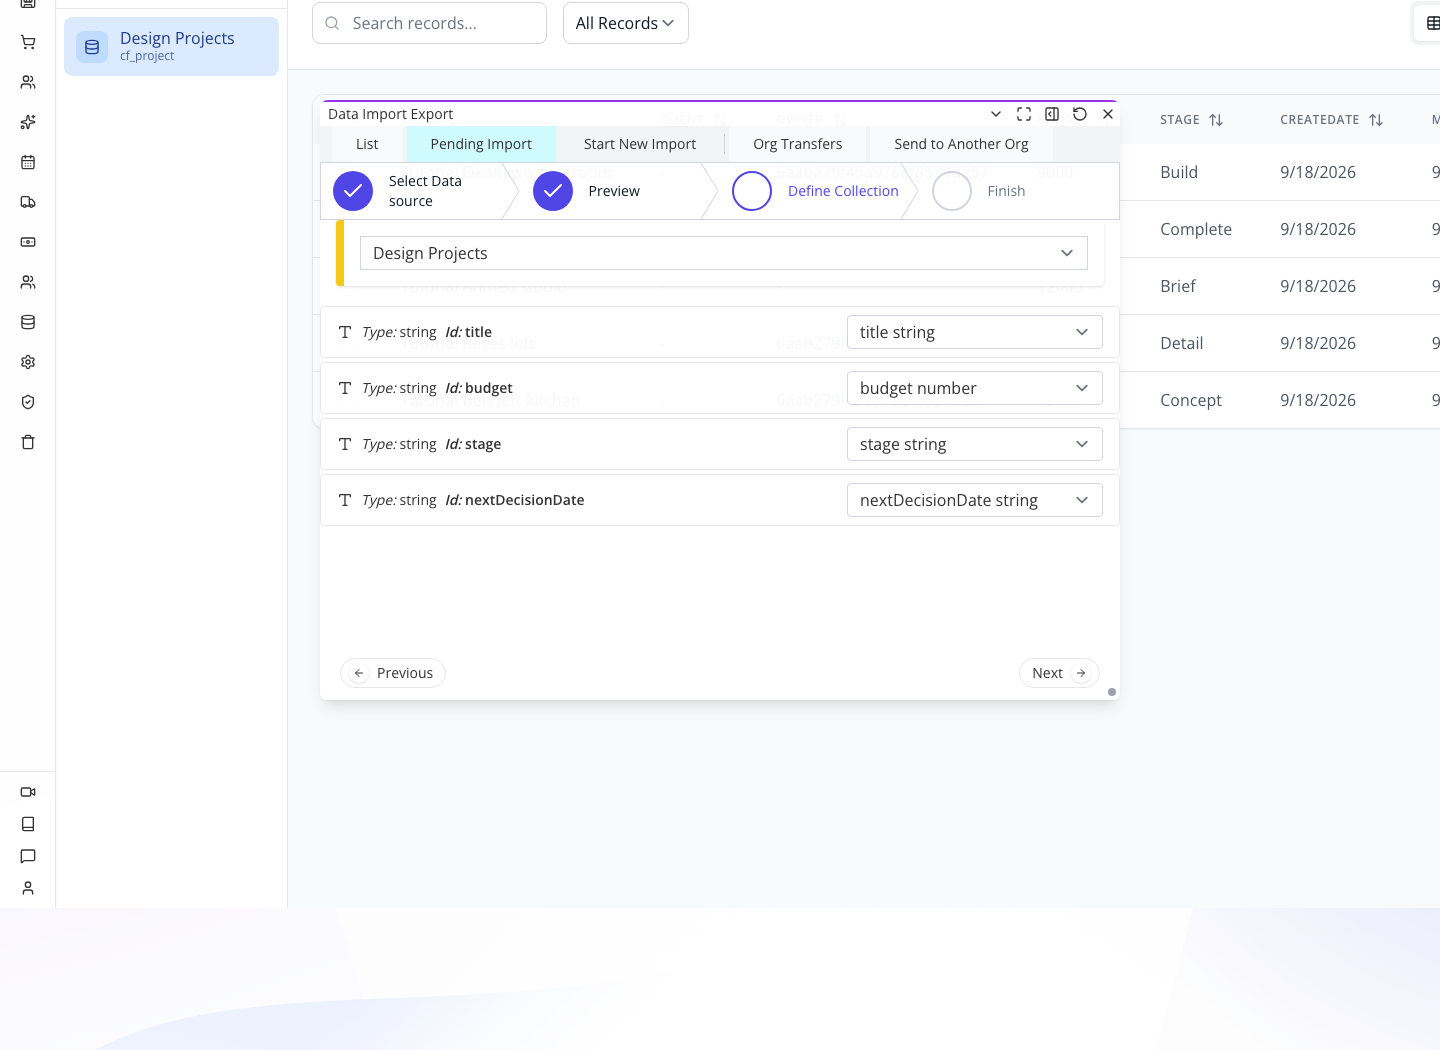
Here budget arrived as text but targets the number field. Check conversion and the final stored numeric value. Previous returns to the input/preview; Next advances after the intended mapping has been chosen.
3. Validate before committing
Why this matters
Validate only checks the planned import without writing its records. Update existing records controls whether the next run creates a duplicate or matches an existing item.
Steps
On Summary enable Validate only. For an existing collection choose the intended match field under Update existing records, or Always add a new record when that is deliberate. Use Record id only when re-importing records carrying their original sk values from the same appropriate context. Submit and inspect the import report, including row failures. Correct invalid rows and run validation again. Compare the collection before and after to verify that the validation run did not add records.
Check the result: Validation results and unchanged collection state agree.
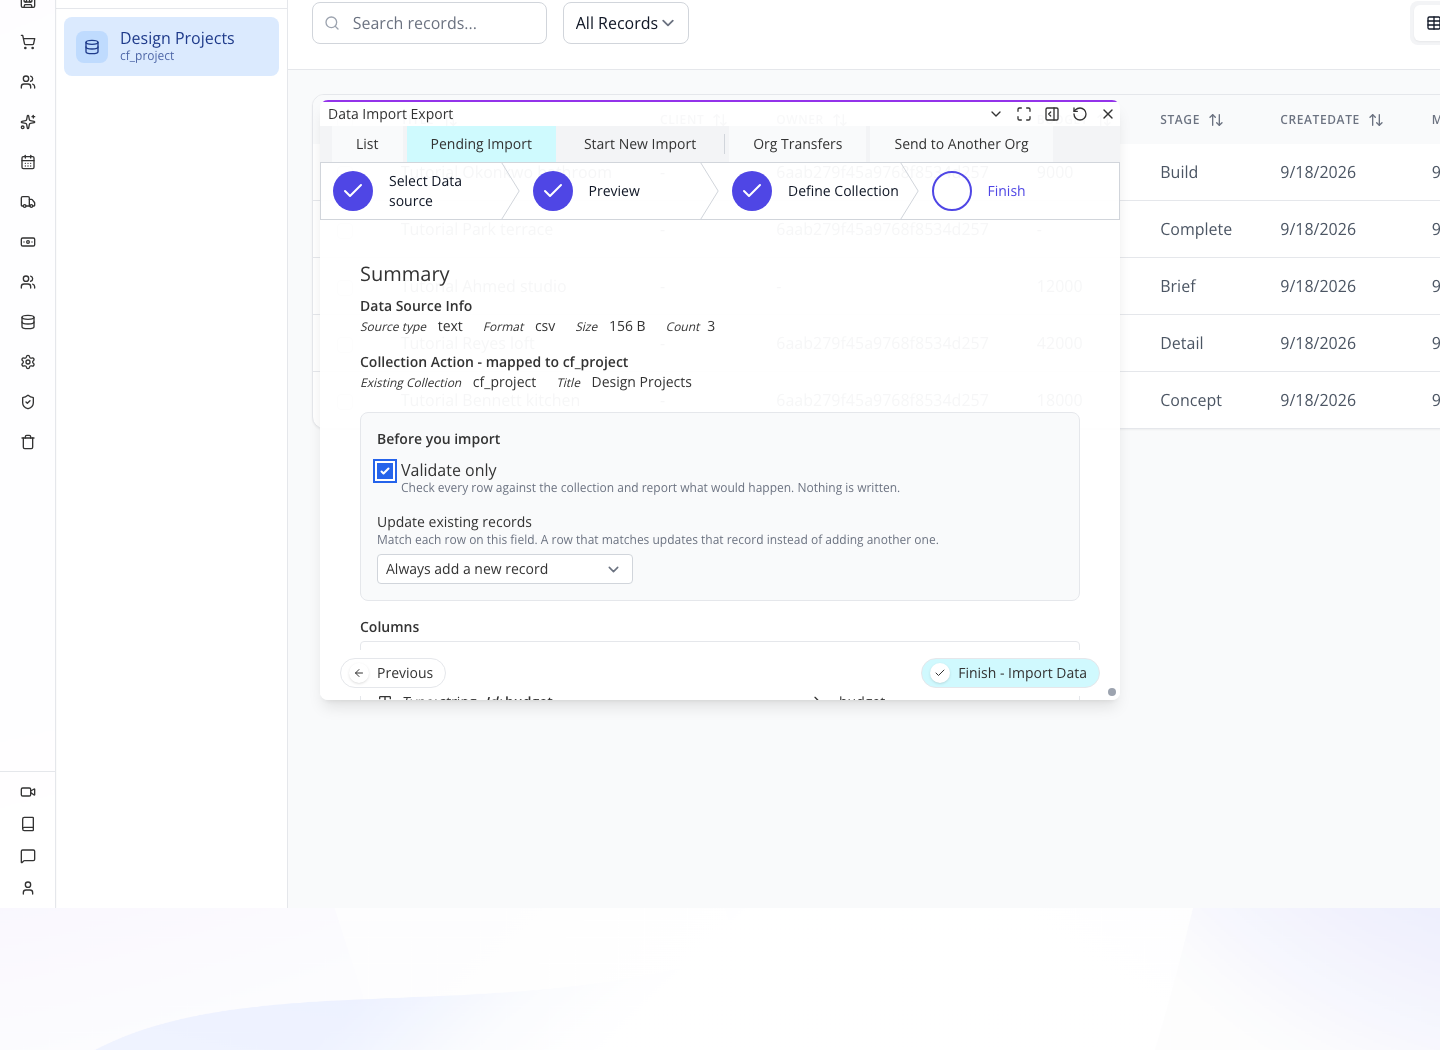
Choose Finish – Import Data only after checking the destination, mappings, validation setting and match field. Wait for the job/report to finish rather than treating submission of the request as completion.
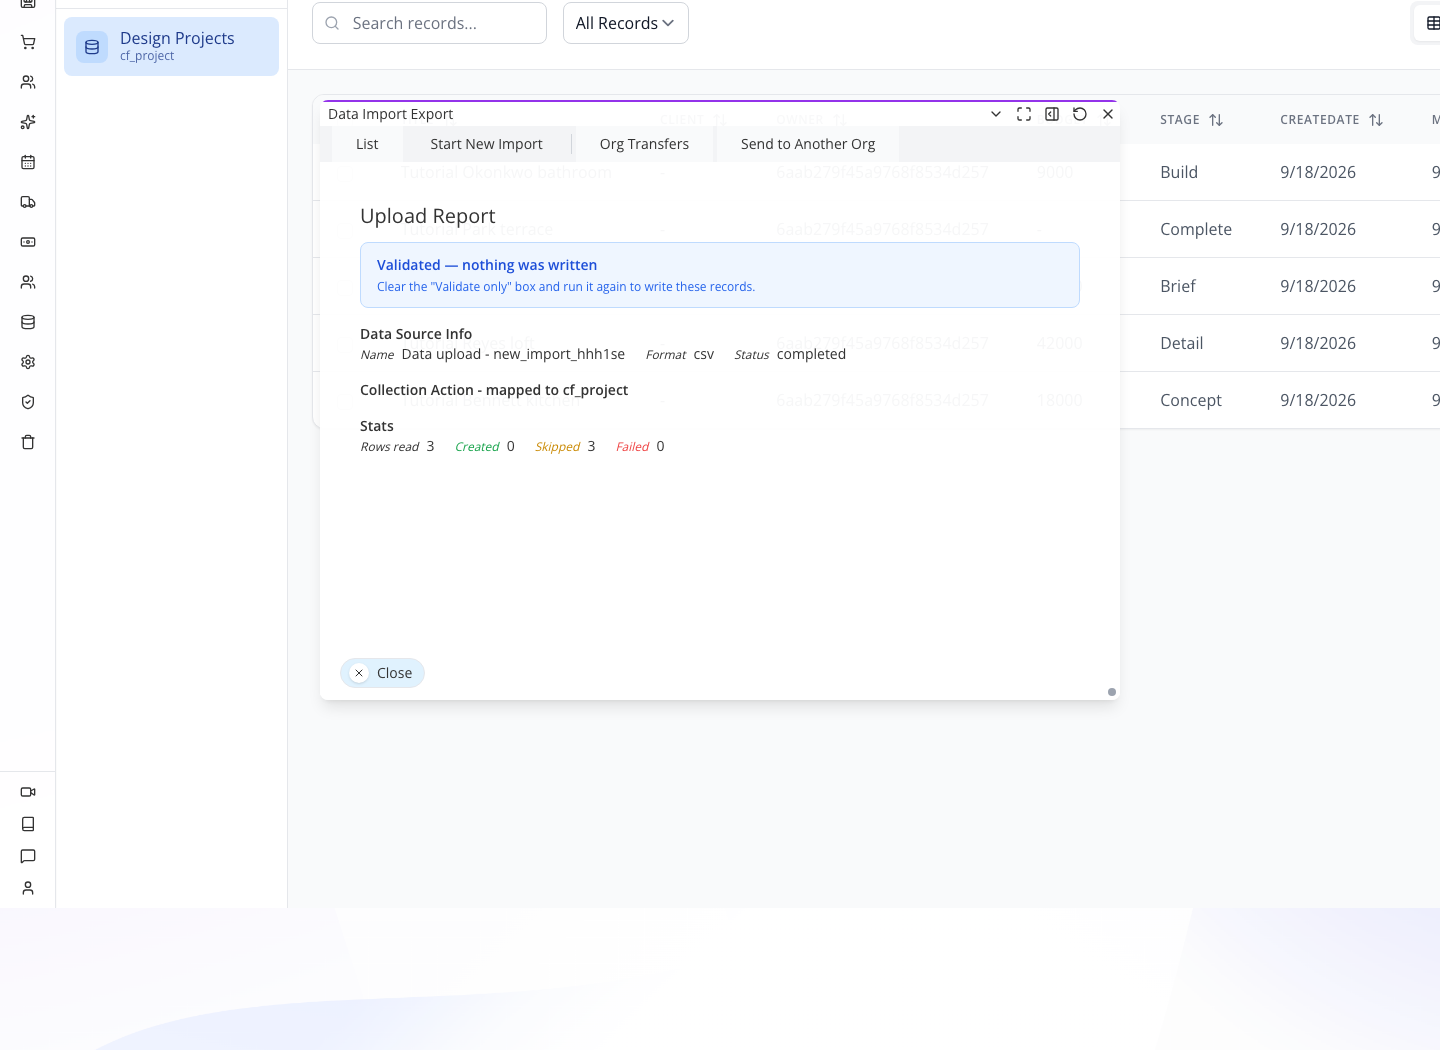
This report records three rows read, zero created, three skipped and zero failed. It establishes that this historical run reported no writes; it does not establish that the deliberately blank title was correctly rejected. Current source maps/coerces and validates before counting dry-run rows as skipped. Repeat a known-invalid-row test in the current build, inspect row errors and verify the destination remains unchanged before trusting validation for a larger input.
4. Import and prove the update behavior
Why this matters
A successful submission may still contain row-level failures. The final collection is the proof.
Steps
Turn off Validate only for the corrected input, retain the same destination and match field, and submit once. Wait for progress/report completion. Open the destination collection and find the known input identifiers; inspect their values. Change one sample value, re-import with the same match field and inspect that same record. Compare the record count to prove it was updated rather than duplicated. If Always add a new record was selected, do not rerun merely because you missed a notice; inspect the collection first.
Check the result: The imported values exist, and the update changes the intended record without an unintended duplicate.
5. Use the uploaded-file and generated-data alternatives
Why this matters
The file path is not identical to pasted text: it skips the preview step and maps differently for an existing collection.
Steps
Choose File Upload and select the intended file. Confirm the format and stored file path in Summary. For an existing collection, the current file path uses field names directly; sk is used for matching and unknown fields are described as kept as-is. Rename input headings to the required destination fields before import rather than promising the text mapping experience. Run Validate only and inspect all reported errors. For Generate Data, inspect the generated content against the schema before committing; generated data is a test input, not evidence of real business records.
Check the result: Each input path is checked according to its actual behavior.
Troubleshooting and recovery
Keep the exact record and operation visible when reading an error. Inspect persisted state before retrying a write; a timeout does not prove nothing happened. Correct the specific cause and verify the resulting record and consumer independently. An enabled feature, successful configuration save or administrative status is not proof of an external delivery, access boundary or money movement. Preserve unsupported behavior rather than simulating success.
Your next check
You can now use the module’s records and controls in context, and check the result at the point where it matters. Return to the relevant chapter for the advanced path and its verification.
Limitations and checks
Current import wizard, datasource, field-mapping, finish and server row-validation source inspected. Historical screenshots were personally reviewed; no fresh import executed in this pass. The inspected wizard does not provide a general export screen; export from the source collection/system is a prerequisite, not an invented button here. Dry-run/upsert UI exists; live row validation, async completion and server matching still require proof.